100% ON-DEVICE · NO ACCOUNT · NO CLOUD SiloLM

Your AI. Your device.
Your data.

SiloLM runs open language models directly on your iPhone — a private AI that sees images, searches the web and drafts your texts, while everything you say stays in your pocket.

DOWNLOAD NOW ▸ SEE FEATURES
// CAPABILITIES

Everything a cloud chatbot does.
Without the cloud.

01

Fully on-device

Open models accelerated by Apple silicon. No servers, no API keys, no queue for someone else's GPU — it even works in airplane mode.
02

Vision

Attach photos and let multimodal models describe, read and reason about what they see. Your images never leave the phone.

03

Web search

Enable the search tool and your local model looks up news, prices and current events in real time — then cites its sources.

04

Reads any URL

Paste a link and the AI fetches the page and digests it for you. Summaries and answers from any article, on demand.

05

iMessage assistant

Draft, rewrite and polish texts inside Messages. Funnier, warmer, shorter — without leaving the conversation.

06

Reasoning control

Dial how hard the model thinks. Instant replies when you're in a hurry, deep step-by-step reasoning when it matters.

// THE EXPERIENCE

Engineered like hardware.
Felt like magic.

⌁ 01 Built for the device in your hand Native performance on iPhone — models tuned for the Neural Engine era.
⌁ 02 An agentic layer, not just a chat Tools, vision and reasoning working together — a small OS for intelligence.
// MODEL LIBRARY

Pick your brain. Literally.

Curated open models tuned for phones. Download, switch, done.

Gemma 4 E4B VISION Google · 4.1 GB Efficient multimodal all-rounder
Qwen 3.5 4B VISION Alibaba · 3.3 GB Strong reasoning, multilingual
Phi-3.5 Mini TEXT Microsoft · 2.4 GB Logic and coding in a small body
Llama 3.2 3B TEXT Meta · 2.0 GB Balanced quality and speed
Qwen 2.5 1.5B TEXT Alibaba · 1.0 GB Instant replies on any recent iPhone
Llama 3.2 1B TEXT Meta · 0.8 GB Featherweight, surprisingly capable
// HARDWARE

Not just an app.
An engine with its own silicon.

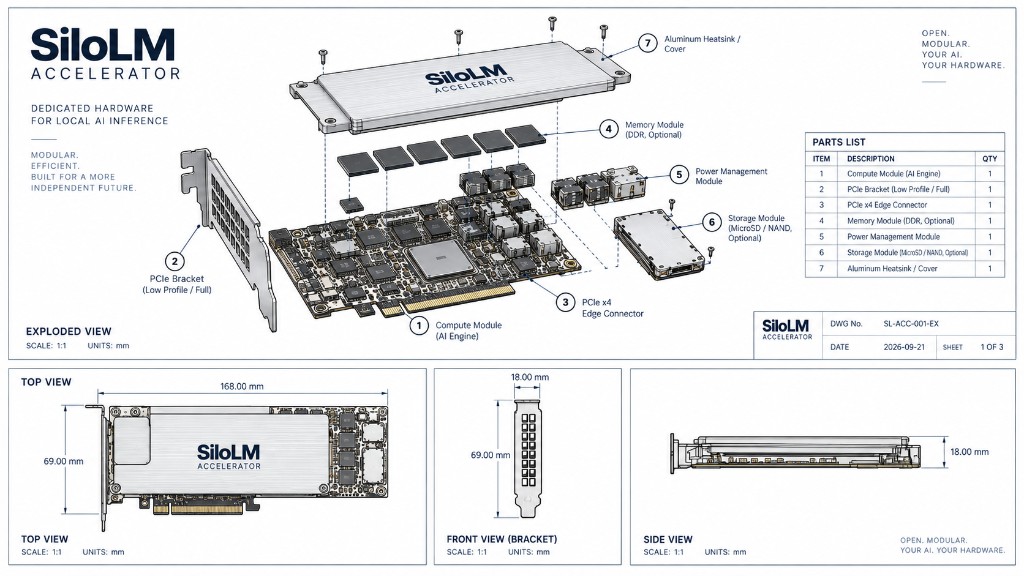
SiloLM stands on llama.cpp — and underneath it we build what almost nobody else does: our own accelerator hardware, designed, verified and programmed in-house.

SiloLM Accelerator — exploded view technical drawing
  • Real silicon, today A parallel compute core designed in-house, running real language models end to end on physical hardware.
  • Proven with the standard everyone can check 1,133 / 1,133 llama.cpp backend conformance tests passed — every weight type, shape and edge case.
  • Next generation: PCIe speed ~30 tokens/second from a device drawing less power than a laptop charger. Load once, generate forever.
EXPLORE THE ACCELERATOR ▸

P R I V A T E B Y A R C H I T E C T U R E

Not a promise.
A physical fact.

Cloud chatbots promise not to misuse your data. SiloLM simply never has it. Your prompts, photos and documents are processed by a model stored on your phone — there is no SiloLM server to send them to.

0bytes of chat data collected
0accounts required
100%works without internet

T H E F U T U R E I S L O C A L

Put an AI in your pocket.
For real this time.

Requires an iPhone with A14 Bionic or newer